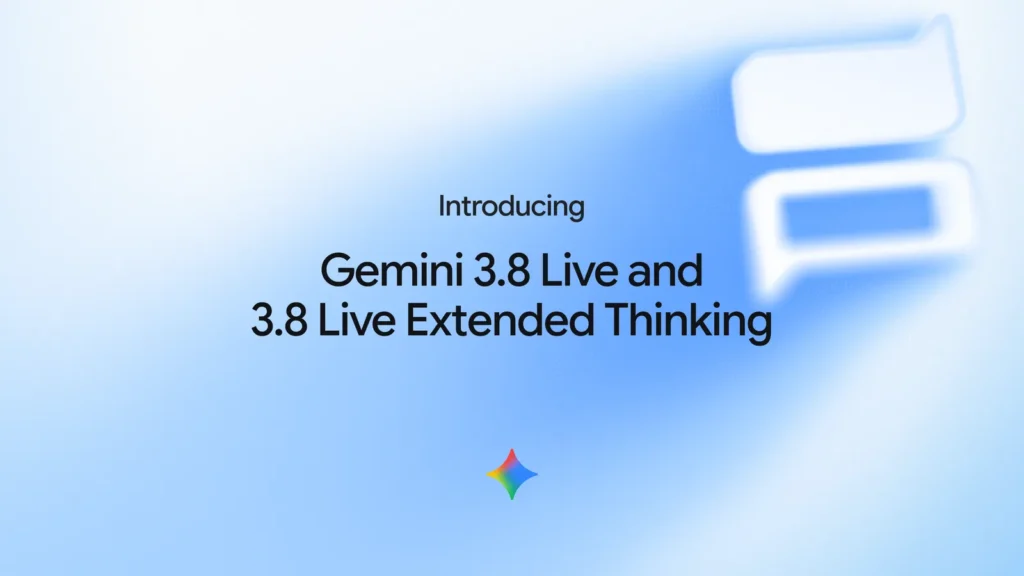
Google Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking both are made to have real natural voice conversations with people. Not the stiff “ask a question, wait for an answer” style but more like talking to another person. On September 15, 2026, Google introduced two new AI voice models. Below is a simple, detailed breakdown of what they are, what makes them different, and how they’re already being used.
Hello tech lover,s if you are a beginner to learn about artificial intelligence and want to become an AI specialist, you must read our simple guides.
- How to become an AI specialist
- What Is Computer Vision A Simple Guide for Everyone
- What Is Deep Learning? A Complete Guide to Deep Learning
- 8 Types of Computer Vision Models Explained (With Examples)
What are Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking Models
What is Gemini 3.8 Live
Gemini 3.8 Live is Google’s fastest and most cost-effective real-time voice AI model. It was released on September 15, 2026. It is built for large-scale everyday conversations. Amazingly, it processes speech and visual input directly in real time by skipping the usual speech-to-text-to-speech delay.
Gemini 3.8 Live automatically detects and switches between 97 languages mid-conversation. It is able to run background tasks like API requests while continuing to talk and make tool calls. While remaining lightweight and affordable enough for heavy use.
What is Gemini 3.8 Live Extended Thinking
Gemini 3.8 Live is extended thinking also Google’s most powerful voice AI model, released on the same day, September 15, 2026. It is built for more complex and multitasking tasks that require deeper reasoning.
It can think and speak fast at the same time using natural verbal cues like “Let me check that.” Acknowledge tasks such as booking and coding from a sketch.
And building out a business plan. That aims to make it suited for enterprise and agentic voice workflows rather than simple, quick exchanges.
What problem are these models solving?
Normal voice assistants often work in three slow steps. They turn your speech into text, think about the text, then turn the answer back into speech. That process causes delay, and it makes it hard for the assistant to be interrupted mid-sentence the way a real person can.
Gemini 3.8 Live and its “Extended Thinking” version are built to fix that. They process audio directly, in real time, so they can respond quickly, get interrupted naturally, and keep a conversation flowing.
Gemini 3.8 Live and 3.8 Live Extended How They’re Different
Google built two versions because voice conversations have a trade-off. Answering instantly versus thinking deeply. You can’t always do both at once. So they split it into two types.
Gemini 3.8 Live
- Built for speed, scale, and low cost.
- Meant for high-volume tasks and everyday conversations.
- Can look at visual input (like your camera or screen) in near real time and use it to give better answers.
- Automatically recognizes when you switch between any of 97 supported languages, mid-conversation, without you needing to tell it.
- Can run tools and background tasks (like API calls) while continuing to talk, instead of pausing until the task is done.
Gemini 3.8 Live Extended Thinking
- Built for harder, multi-step problems.
- Can reason and speak at the same time. Meaning it can say something like “Let me check that” while it’s still working, instead of going silent.
- Gives live updates while it works through a task in the background, so you always know what it’s doing.
- Aimed at more complex, agent-like tasks, the kind of thing a business or enterprise tool would need.
How well do they perform?
According to Google’s announcement 3.8 Live Extended Thinking currently holds the top overall spot on a third-party ranking called the Artificial Analysis Speech-to-Speech Quality Index. It gained a score of 82.6. It also leads in task-completion tests scoring 68.6% on a benchmark called τ-Voice and 35.1% on a banking-specific voice-agent test from Sierra. On a benchmark testing reasoning through audio it scored 97.7%.
The standard Gemini 3.8 Live model came in second place in a separate ranking called the Speech Agent Arena. While staying notably cheaper to run which fits its role as the “fast and efficient” option rather than the “smartest” one.
Real Examples Google showed Off Gemini 3.8 Live and Gemini 3.8 Live Extended
Google’s announcement included several demo videos to show what these models can actually do.
- Employee onboarding: Gemini 3.8 Live guiding a new employee through onboarding steps in real time. Using visual context (like what’s on their screen) to answer questions as they come up.
- Playing chess: The model watches a chessboard and plays a game near instantly, combining vision, reasoning, and natural back-and-forth conversation.
- Sketch to code: Extended Thinking turning a rough hand drawn sketch into a working React component guided by spoken feedback as it worked.
- Multi-step bookings: Extended Thinking coordinating something like a travel or reservation booking that needs several steps and background actions. All without breaking the flow of conversation.
- Business planning out loud: Gemini 3.8 Live builds out a business plan or marketing toolkit just from someone talking through their ideas.
Where You Can Actually Use 3.8 Live and 3.8 Live Extended Thinking
Both models are rolling out starting the day they were announced across a few different surfaces.
Developers: Available through the Gemini API and Google AI Studio.
Enterprises: In private preview through Gemini Enterprise, with Extended Thinking also coming to Google Workspace business customers.
Everyday users: Gemini 3.8 Live is available in Search Live. Extended Thinking is available in the Gemini app and for Google AI Pro/Ultra subscribers inside Docs, Gmail, and Keep.
MAny other developer platforms including Agora LiveKit, Pipecat, LangChain, and Vercel are also building support for these models. Handling the complicated real-time streaming work so developers can focus on the actual user experience.
Safety Note
Every piece of audio these models generate is watermarked using Google’s SynthID technology. That watermark is invisible to the human ear but detectable by software. And it’s meant to help people tell AI-generated audio apart from real recordings a safeguard against misuse like deepfakes or misinformation.
Gemini 3.8 Live vs GPT-Live-1
1: Architectural Paradigm Integrated vs. Modular
The foundational difference between OpenAI’s and Google’s 2026 voice releases lies in where the reasoning “brain” lives.
- Gemini 3.8 Live and Extended Thinking: An integrated single model design. The voice, visual grounding, and deep reasoning run within the same core model context. It handles simultaneous reasoning and speech. And narrating its progress and acknowledging requests while executing multi-step logic in parallel.
- GPT-Live-1: A modular full-duplex voice interface layer. It acts as a dedicated real-time audio orchestration layer that streams inputs and outputs instantly. While delegating complex reasoning or tool orchestration to a separate backend model (e.g., GPT-5/GPT-6 series).
Pricing & Billing Model
| Metric / Dimension | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking | GPT-Live-1 |
|---|---|---|---|
| Billing Structure | Token / Stream Metered | Token / Stream Metered | Per-Second Session Flat Rate |
| Audio Input | $0.005 / min ($3.00 / 1M tokens) | $0.005 / min ($3.00 / 1M tokens) | $0.050 / min (Voice Layer Only) |
| Audio Output | $0.018 / min ($12.00 / 1M tokens) | $0.018 / min (Includes thinking tokens) | $0.050 / min (Voice Layer Only) |
| Backend / Reasoning Cost | Included | Included | Billed Separately (Backend LLM rates apply) |
| Estimated Hourly All-In Cost | ~$0.84 – $1.38 / hour | ~$1.50 – $3.50 / hour | ~$4.47 – $5.83+ / hour |
Gemini 3.8 is considerably cheaper for high-volume enterprise deployments. Because OpenAI’s GPT-Live-1 bills $0.05/minute solely for the voice stream. Attaching a complex reasoning backend adds separate token costs on top. Conversely, Google bundles background reasoning directly into its streaming audio output rate
2: Latency & Response Dynamics
| Latency Metric | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking | GPT-Live-1 |
|---|---|---|---|
| Conversational Turn-Taking | Ultra-low (Streaming Native) | Instant Acknowledgement (~200ms) + Conversational Thinking | ~0.798s (Official) / ~1.24–1.30s (Independent Tests) |
| Time-to-First-Audio-Chunk | Instant streaming | ~200–300ms (Acknowledgement) | ~300–600ms (Voice Layer) |
| Handling Complex Queries | Direct execution pause | Simultaneous Progress Narration | Delegates to backend; maintains backchannel filler |
| Barge-in / Interruption Handling | Native | Adaptive (resets context path without full stop) | Native Full-Duplex |
- GPT-Live-1 delivers fast turn-taking for simple dialogue (~800ms). However, in real-world agentic tasks involving external delegation, total response latency stretches out.
- Gemini 3.8 Live Extended Thinking bypasses perceived latency by filling the gap conversationally. Instead of remaining silent during complex reasoning, it provides instant spoken micro-acknowledgments and live status updates (“Let me check that calendar for you…”) while computing in parallel.
3. Benchmark Performance Gemini 3.8 live Vs GPT Live 1
| Benchmark / Evaluation | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking | GPT-Live-1 |
|---|---|---|---|
| Speech-to-Speech Quality (Artificial Analysis) | 78.2 | 82.6 (#1 Leaderboard) | 79.8 |
| Agentic Task Completion (τ-Voice / Tau3) | 62.1% | 68.6% | 83.6% (With high-end backend) / 45.7% (Base) |
| Big Bench Audio | 94.1% | 97.7% | 92.4% |
| Multi-Language Mid-Sentence Switching | 97 Languages | 97 Languages | Supported (Auto-Detect) |
Gemini Real Time Voice and Speech Models
Models designed specifically for low-latency, bidirectional audio streaming, conversational turns, and speech synthesis.
- Gemini 3.8 Live: Real-time speech-to-speech model supporting live camera feeds, 97 languages, and instant tool calling during speech.
- Gemini 3.8 Live Extended Thinking: Voice model capable of simultaneous background reasoning and progress narration without speech pauses.
- Gemini 3.1 Flash Live: Preview model optimized for live, low-latency audio-to-audio streaming interfaces.
- Gemini 2.5 Pro TTS & 2.5 Flash TTS: Specialized Text-to-Speech models designed for studio-grade audio narration and fast voice generation.
Conclusion
Think of it this way Gemini 3.8 Live is the fast, everyday conversational assistant good for quick help. Such as translation on the fly and casual tasks. Gemini 3.8 Live Extended Thinking is the version you’d reach for when the task is complicated. Like multi-step bookings, coding help, or business planning. Because it can think it through out loud without losing the natural rhythm of a conversation.
If you already have an established multi-agent infrastructure powered by OpenAI’s ecosystem and want an isolated. Highly steerable full-duplex voice layer that routes tasks to custom external agents.
I am truly thankful to the owner of this website who has shared this fantastic piece of writing at at this place.